 Author: Kamil Kosiorek „Kosior” — owner of Vis-Sol, author and process owner
Case study / Linux · processes · shared hosting
Each mechanism made sense in isolation. The failure appeared when workers, cron, watchdogs, supervisors and orchestration independently managed the same lifecycle. The result was rapid PID growth, a RAM spike and risk for other services sharing the same resource budget.
100 → 48
active processes after reorganising the execution layer; about 52% fewer than before optimisation
peak ≈360 PIDs
>2.6 GB RAM
one lifecycle owner per role
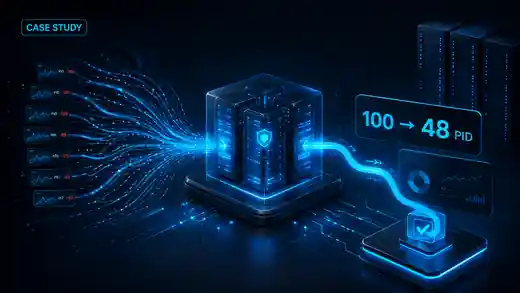
Vis-Sol case study 100 → 48 PIDs · controlled lifecycle and monitoring
Why can PID counts keep growing even when individual workers are correct?
Because several correct mechanisms can independently manage the same role. Cron, a watchdog, a supervisor and a worker's own loop can start new instances without one shared ownership model.
The problem was not one worker. It was the absence of one process-ownership model.
Several independent execution mechanisms were active in the environment. Some workers had their own loop, cron started other jobs, watchdogs reacted to service state, supervisors kept processes alive and an orchestrator started additional components.
Each mechanism was reasonable on its own. The whole-system view showed that the same function could be started more than once. If an earlier instance had not finished before the next trigger, another instance appeared; child processes accelerated PID growth further.
New process on schedule
the scheduler did not know whether the previous instance was still active
Restart from a signal
a missing signal could be interpreted as a missing process
Own loop and child processes
long-running work could create additional helper processes
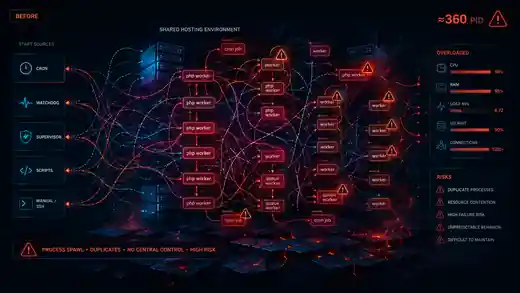
Before optimisation. Cron, watchdogs, supervisors, scripts and manual starts created overlapping start and restart paths.
A PID alone is not enough
A process number confirms an entry in the process table, but it does not describe the role, health state or lifecycle owner. Before restarting anything, supervision should verify process identity, health, the child-process tree and the mechanism authorised to manage that role.
Architecture decision: 1 role = 1 process owner = 1 start mechanism
Before adding another worker, check whether the function already exists. If it does, update the existing mechanism or replace it. Do not start a new version beside the old one merely because the earlier instance is assumed to have stopped.
Use a queue or explicit parallelism
If two tasks should not run at the same time, put them behind one queue. If parallel execution is required, make it part of the architecture: each domain gets an explicit worker, responsibility and process budget.
control point and ownership
MLP / SEMANTIC
separate compute domains
its own work queue
supervision without multiplication
For frequent cycles, prefer a worker to repeated cron starts
For frequently repeated work, one long-running worker can be a better model: run → wait → run again → healthcheck. Cron remains appropriate for genuinely periodic jobs such as backups, housekeeping, daily reports or audits.
A watchdog should diagnose before restarting
A missing signal does not necessarily mean that the process is gone. Before a restart, check the main process, child processes, health state, service owner and whether another mechanism is supervising the same role.
is the process really absent
did child processes remain
is the process stalled
OWNER → RESTART
restart only after excluding duplication
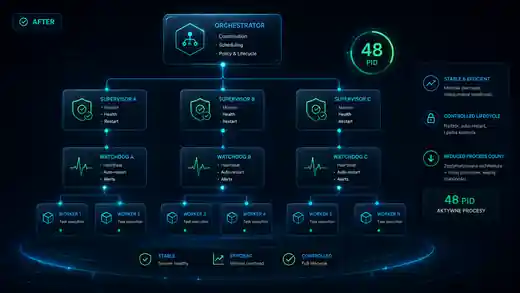
After optimisation. One ownership model, an explicit lifecycle, controlled health checks and a predictable process budget.
Result: fewer processes were a consequence; predictability was the goal
After reorganising workers, start sources and supervision, the active process count fell from about 100 to 48. More importantly, the conditions that had allowed the environment to escalate into hundreds of PIDs were constrained. The reduction is not a universal benchmark; it describes this specific environment and incident.
Shared-hosting blast radius
When several projects share one resource budget, process or memory growth in one application can affect other services. Monitoring therefore needs to cover the account as a whole: user PIDs, RAM, process trees, active schedules and supervision mechanisms.
Operator suggestions — observe first, change second
The commands below shorten diagnosis and make the work sequence explicit. Record a baseline, make one change, then re-check PID count, RAM and health.
1. Count user processes
ps -u "$USER" -o pid= | wc -l
Record the baseline before changing anything.
2. Largest processes by RAM
ps -u "$USER" -o pid,ppid,rss,%mem,cmd --sort=-rss | head -n 25
Separate raw PID count from actual memory cost.
3. Duplicated roles
pgrep -af 'worker|orchestrator|watchdog|supervisor'
Check whether several mechanisms are starting the same function.
4. Parent → child process tree
pstree -ap "$USER"
Check child processes before restarting a parent.
Six design rules
- Check whether the role already exists before adding another implementation.
- One worker should have one lifecycle owner.
- Design parallel execution explicitly.
- Cron is not a supervisor.
- A watchdog diagnoses before restarting.
- Monitor the environment, not only one service.
A similar problem?
We can review your processes, PIDs and supervision model.
Without adding another layer blindly — diagnosis first, then ownership and lifecycle cleanup.
FAQ
No. A PID confirms that a process exists, but it does not describe the role, health state or lifecycle owner.
Usually not. A long-running worker should have one explicit start and supervision mechanism.
If it restarts a service without checking the process, child processes and ownership, it can create a duplicate.
No. Parallel execution is valid when instance count, queues, ownership and resource budget are explicitly controlled.
100 → 48 belongs to this environment
The key result is controlled ownership and a predictable process budget.
Queue and latency (PL)
Shared-hosting continuity (PL)
All knowledge materials
A similar process?
Count processes first, then establish ownership.
We can review worker lifecycle, cron, watchdogs, supervisors and the impact of the execution layer on the available hosting budget.
See also: System and API integration · Business process automation